Market quality describes how a market supports price discovery and the exchange of risk. Execution quality describes what happened to a particular order relative to a clearly defined reference. They overlap, but they are not the same thing.
A narrow displayed spread can coexist with poor fills. A deep-looking book can change before an order reaches it. A fast confirmation does not prove that the decision used a current market snapshot. These distinctions matter because a dashboard can display an observed metric while the user supplies an interpretation that the metric does not justify.
This guide provides a measurement framework. It does not rank venues, promise better execution, or recommend how to place an order. The material is educational and is not financial advice. The Kingfisher visualizations discussed here are analytical context, not a record of a user's exchange order or a substitute for exchange confirmations.
Separate observation from interpretation
Market-quality work becomes clearer when every statement is assigned to one of three layers.
Observed data is a recorded value tied to a source and time: the best displayed bid, best displayed ask, quoted size, trade print, order status, or fill price.
Derived metrics are calculations based on observations: spread, midpoint, depth within a price band, volume-weighted fill price, slippage, or price impact.
Interpretation is the explanation attached to those measurements: the book was resilient, an order moved the market, one venue was more executable, or a period was unusually stressed.
The first two layers can often be reproduced if the inputs, units, timestamps, and formulas are preserved. The third requires caution. Several mechanisms can produce the same visible result, and incomplete data may hide a more plausible explanation.
For example, “the best bid-ask spread in this snapshot was two quote increments” is an observation-derived statement. “The venue therefore offered the best execution” is an interpretation that also requires order size, fees, available depth, queue position, order type, delay, and actual fills.
The core measurements
Bid-ask spread
The bid-ask spread is the difference between the best displayed ask and best displayed bid at a specified time. It can be expressed in quote currency, ticks, or basis points relative to a reference price.
The spread is meaningful only when its construction is explicit:
- Which instrument and venue supplied the quote?
- Were bid and ask captured from the same book state?
- What timestamp and clock source were used?
- Was the value raw, averaged, or sampled?
- Was the quote crossed, locked, missing, or stale?
- Were fees excluded or incorporated?
A single narrow snapshot does not characterize an entire session. A time series can show the distribution of spreads, but sampling frequency influences what it captures. Slow sampling may miss brief widening; event-driven sampling may overweight busy intervals. Neither is automatically wrong, but the method needs to be stated.
Displayed market depth
Market depth summarizes visible resting quantity at one or more price levels. Common variants include quantity at the top of book, cumulative quantity within a fixed price distance, or the notional required to move through several levels.
Displayed depth is not guaranteed executable depth. Orders can be filled by someone else, cancelled, added, or repriced between observation and arrival. Hidden orders may not be included. Different feeds can aggregate levels differently, and a contract quantity may require conversion before it is comparable with another instrument.
A careful depth record therefore includes the side, price band, unit, conversion method, timestamp, and snapshot sequence. If the measurement uses notional value, document which price converted contract quantity. If it combines venues, document how symbols and quote currencies were normalized.
Slippage
Slippage is the difference between a fill and a chosen benchmark. The benchmark could be the midpoint at decision time, the midpoint when the order was submitted, the best quote on arrival, an interval benchmark, or another documented reference.
There is no useful slippage number without the benchmark definition. Two analysts can calculate different values from the same fill because they selected different reference times. That is not necessarily an error; it means they measured different parts of the process.
For a multi-fill order, first define the quantity-weighted average fill price. Then compare it with the benchmark using a sign convention that makes adverse and favorable outcomes unambiguous. Preserve partial fills and unfilled quantity rather than treating the completed portion as the whole order.
Slippage can reflect spread crossing, depth consumption, market movement during the order's journey, queue position, venue rules, or a combination of these. The metric measures an outcome. On its own, it does not identify the cause.
Price impact
Price impact asks how market prices changed around an order or trade. It is often confused with slippage. Slippage compares execution with a benchmark; impact attempts to characterize the market response associated with the event.
Impact measurement needs an event time, a pre-event reference, one or more post-event horizons, and a rule for handling other activity in the same interval. A midpoint that moves after a fill may indicate persistent impact, temporary dislocation, new information, or unrelated orders. Causal claims require more than a before-and-after chart.
Fill quality
Fill quality is multidimensional. Relevant observations can include:
- completed and unfilled quantity;
- average and individual fill prices;
- number and timing of partial fills;
- order acknowledgements, rejections, and cancellations;
- benchmark price at defined stages;
- explicit fees or rebates;
- whether the requested conditions were respected.
Reducing all of this to one score can hide important tradeoffs. A fill close to the midpoint may still be incomplete. A complete fill may have crossed several levels. A limit order that did not execute has no realized slippage but still has an outcome worth recording.
Time is part of every value
Market data without usable time metadata is difficult to audit. At minimum, distinguish:
- event time: when the source says the market event occurred;
- receive time: when a collector received it;
- processing time: when a transformation or aggregation ran;
- display time: when the user interface rendered the result;
- order lifecycle times: when an order was created, acknowledged, filled, cancelled, or rejected.
These clocks answer different questions. Comparing a fill timestamp with a chart render time can create a false sequence. Clock drift can also reverse events that happened close together.
Good analysis records the clock source and does not claim more temporal precision than the pipeline supports. If timestamps have coarse resolution, do not infer a fine-grained ordering. If a source changes its timestamp semantics, measurements before and after the change may not be directly comparable.
Units, symbols, and contract identity
Crypto instruments that look similar can have different contract multipliers, collateral, quote currencies, settlement rules, index construction, and tick sizes. Before comparing venues or aggregating data, build an instrument identity table.
Useful fields include venue, canonical underlying, venue symbol, contract type, quote asset, collateral asset, multiplier, tick size, quantity unit, and price unit. Record the version date because specifications can change.
Unit errors often look plausible. A field called “size” might mean contracts on one source and base-asset quantity on another. A notional conversion may use last price in one calculation and midpoint in another. Aggregating those values without normalization creates a precise-looking but invalid result.
Missingness is data, too
A blank interval can mean no event occurred, the feed disconnected, the source returned an error, the instrument was unavailable, or a filtering rule removed the value. Replacing every blank with zero erases those distinctions.
A robust dataset uses explicit states such as observed zero, unavailable, delayed, invalid, and not applicable. It also preserves quality flags through downstream calculations. An aggregate should not silently appear complete when one component venue is absent.
Corrections deserve the same care. If late or revised events alter a historical calculation, record the revision time and the affected interval. Reproducibility requires knowing which data version produced a result.
A controlled venue-comparison protocol
A fair comparison begins with a question narrow enough to test. “Which exchange is best?” is too broad. A reproducible study might instead compare displayed spread and depth for equivalent instruments during the same pre-defined windows, or compare a user's own fills against the same benchmark definition.
The protocol should specify:
- instrument equivalence and exclusions;
- observation period and time zone;
- source and timestamp semantics;
- sampling method;
- unit conversions;
- treatment of missing or crossed books;
- fee assumptions, if fees are included;
- aggregation statistics;
- uncertainty and known blind spots;
- a rule for preserving all observations, not only favorable examples.
Results should be reported as distributions rather than a single memorable snapshot. Medians alone can hide stressed intervals; extremes alone can exaggerate rare events. Quantiles, missing-data rates, and sample counts give readers more context, provided the method remains visible.
Even a strong study applies to its instruments, dates, order sizes, and methodology. It does not establish a permanent universal ranking.
How liquidation analytics fit into the picture
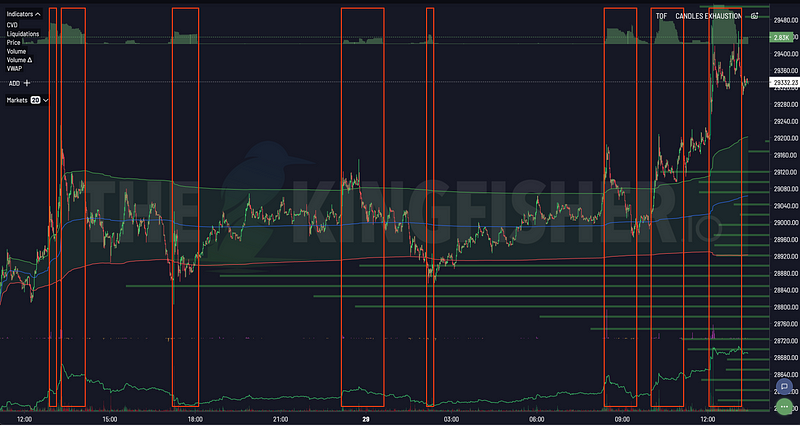
A liquidation map estimates potential liquidation concentrations, while a liquidation heatmap adds their modeled evolution over a displayed period. These views can provide leverage context for research about stressed markets, but they do not measure a user's spread, queue position, order path, or realized fill.
A visually intense modeled zone is not executable liquidity. It should not be substituted for an order book. Likewise, observing price near a modeled zone does not establish that a later fill outcome was caused by liquidations.
The defensible workflow is to keep the datasets separate:
- record the model output and its settings;
- record market-quality observations with their own timestamps and units;
- record actual order outcomes from the exchange account;
- align them only at a resolution supported by the timestamps;
- label any relationship as interpretation unless the study design supports a stronger claim.
The Kingfisher app can be one analytical source in that workflow. Current screens, supported instruments, access conditions, and product definitions should be verified in the authenticated app and documentation. This page does not assert a particular feed speed, venue coverage, or execution capability.
An audit worksheet
Before interpreting a market-quality chart or execution report, answer the following questions:
| Area | Audit question |
|---|---|
| Identity | Is this the exact instrument and contract intended? |
| Source | Which venue, feed, or account produced each field? |
| Time | What do the timestamps mean, and are clocks comparable? |
| Units | Are quantity, price, and notional normalized consistently? |
| Completeness | Which intervals or components are missing? |
| Formula | Can another person reproduce each derived metric? |
| Benchmark | Which reference defines slippage or impact? |
| Outcome | Are partial fills, rejections, and unfilled quantity retained? |
| Interpretation | Which statements go beyond direct observation? |
| Limitation | What relevant information is not available? |
This worksheet is deliberately plain. Reliable market-quality analysis depends more on disciplined definitions than on a dramatic dashboard.
What data accuracy means in practice
“Accurate” should not be used as an unqualified marketing label. A dataset can match its source and still be unsuitable for a particular question. A display can render correctly while the underlying symbol mapping is wrong. A calculation can be arithmetically correct but use timestamps that refer to different stages.
Operational data quality is better expressed through testable properties:
- source fidelity;
- valid instrument mapping;
- documented units;
- coherent timestamps;
- explicit missingness;
- deterministic transformations;
- traceable revisions;
- reproducible formulas;
- visible limitations.
These properties make an analysis auditable. They do not remove market uncertainty or guarantee any execution outcome.
FAQ
Does the narrowest spread identify the best venue?
No. A spread snapshot excludes depth, fees, queue position, order size, timing, rejected quantity, and actual fills. It is one measurement in a broader comparison.
Is displayed depth available to execute?
Not necessarily. The visible book can change before an order arrives, and displayed quantity may be cancelled, consumed, replenished, or supplemented by hidden liquidity.
Are slippage and price impact the same?
No. Slippage compares a fill with a defined benchmark. Price impact examines market-price changes around an event and requires additional assumptions about timing and causality.
Can a liquidation heatmap measure execution quality?
No. It provides model-based leverage context. Execution quality requires order and fill records plus a documented benchmark.
Does this guide provide financial advice?
No. It is an educational measurement framework. It does not recommend a venue, order, position, or transaction.
For related concepts, see the liquidation-map guide, crypto calculators, and The Kingfisher's documented history.